Where it runs, and what it reaches
Server location sets your jurisdiction. The number of systems connected sets whether the answer is complete. Both get settled before a scan starts.
- Deployment models
- 3
- Source adapters
- 200+
- Index location
- Wherever you put the server
- Scan access
- Read only
- Outbound connection
- Not required for discovery
Three deployment models
The model you pick decides what your team operates and what gets operated for you. Everything else about the product stays the same.
| Your own servers | A cloud region you control | Hosted service | |
|---|---|---|---|
| Index location | Your infrastructure | Your tenancy, region of your choosing | Operated for you |
| Who runs the server | Your team | Your team | The vendor |
| Jurisdiction control | Complete | Complete | Confirmed by contract |
| Outbound connection | Not required for discovery | Within your cloud account | Standard hosted access |
| Typical fit | Government, healthcare, defence work | Enterprises already standardized on a cloud | Teams that want the capability without operating a server |
Jurisdiction is a deployment choice
GEODI runs inside Canada, the United States or Mexico depending on where you put the server. Data residency stops being a vendor promise and becomes a fact about your own topology.
Two processing paths are worth naming, since they are the ones a privacy reviewer will interrogate.
Source coverage
More than 200 adapters in total. Content is processed identically whatever container it arrives in, so a spreadsheet on a share, the same file attached to an email, and a record inside a database are treated the same way.
- Total adapters
- 200+
- Scanned documents
- OCR, read on the server
- Mail attachments
- Opened and indexed as content
- Databases
- Sampling by record count
- Endpoints
- Through the agent
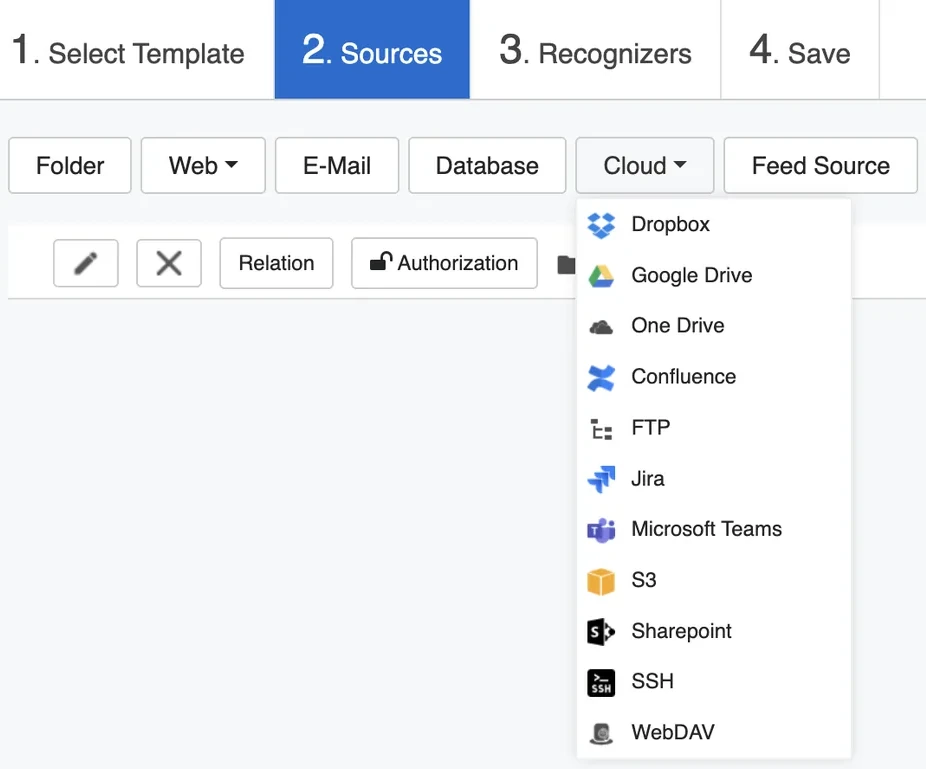
Files and storage
- Folder and network share
- FTP
- SSH
- WebDAV
- Amazon S3
Cloud drives and collaboration
- Dropbox
- Google Drive
- One Drive
- SharePoint
- Microsoft Teams
- Confluence
- Jira
Mail, databases and the rest
- Exchange and mail platforms
- Relational databases
- Web content
- Feed sources
- Endpoints through the agent
The list above names the connectors asked about most often. Send the systems you run and coverage gets confirmed against them directly.
A scan holds no write access
Indexing runs read only. Remediation is a separate switch, turned on per source with credentials you scope and revoke independently. A misconfigured scan has no rights to change a file.
Every action that does change something writes a record naming the account, the target and the time.
| Operation | Access needed |
|---|---|
| Discovery and indexing | Read only |
| Classification | Read only |
| Masking for display | Read only |
| Remediation | Enabled per source, separate credentials |
How big does the server need to be
Sizing follows the volume under management and how many sources run concurrently. A departmental pilot on one share is a different machine from an enterprise index across sixty systems, and the sizing conversation happens before a quote rather than after.
Can we move deployment model later
Yes. Moving between on-premises, private cloud and hosted is a commercial and technical conversation rather than a new purchase.
What if a system we use is not on the list
Send it over. The published list names the connectors asked about most often out of more than 200, so an absence from the list is not an absence from the product.
Does a scan slow the source system down
Sampling by record count keeps a first pass quick on a large repository, and scheduled indexing puts the heavier runs outside working hours.
Send the systems and coverage gets confirmed first
Tell us which platforms hold the data. We check each one against the adapter list and come back before anyone books a meeting.